Tagged with
Kubernetes
21 May 2026 09:00 AM
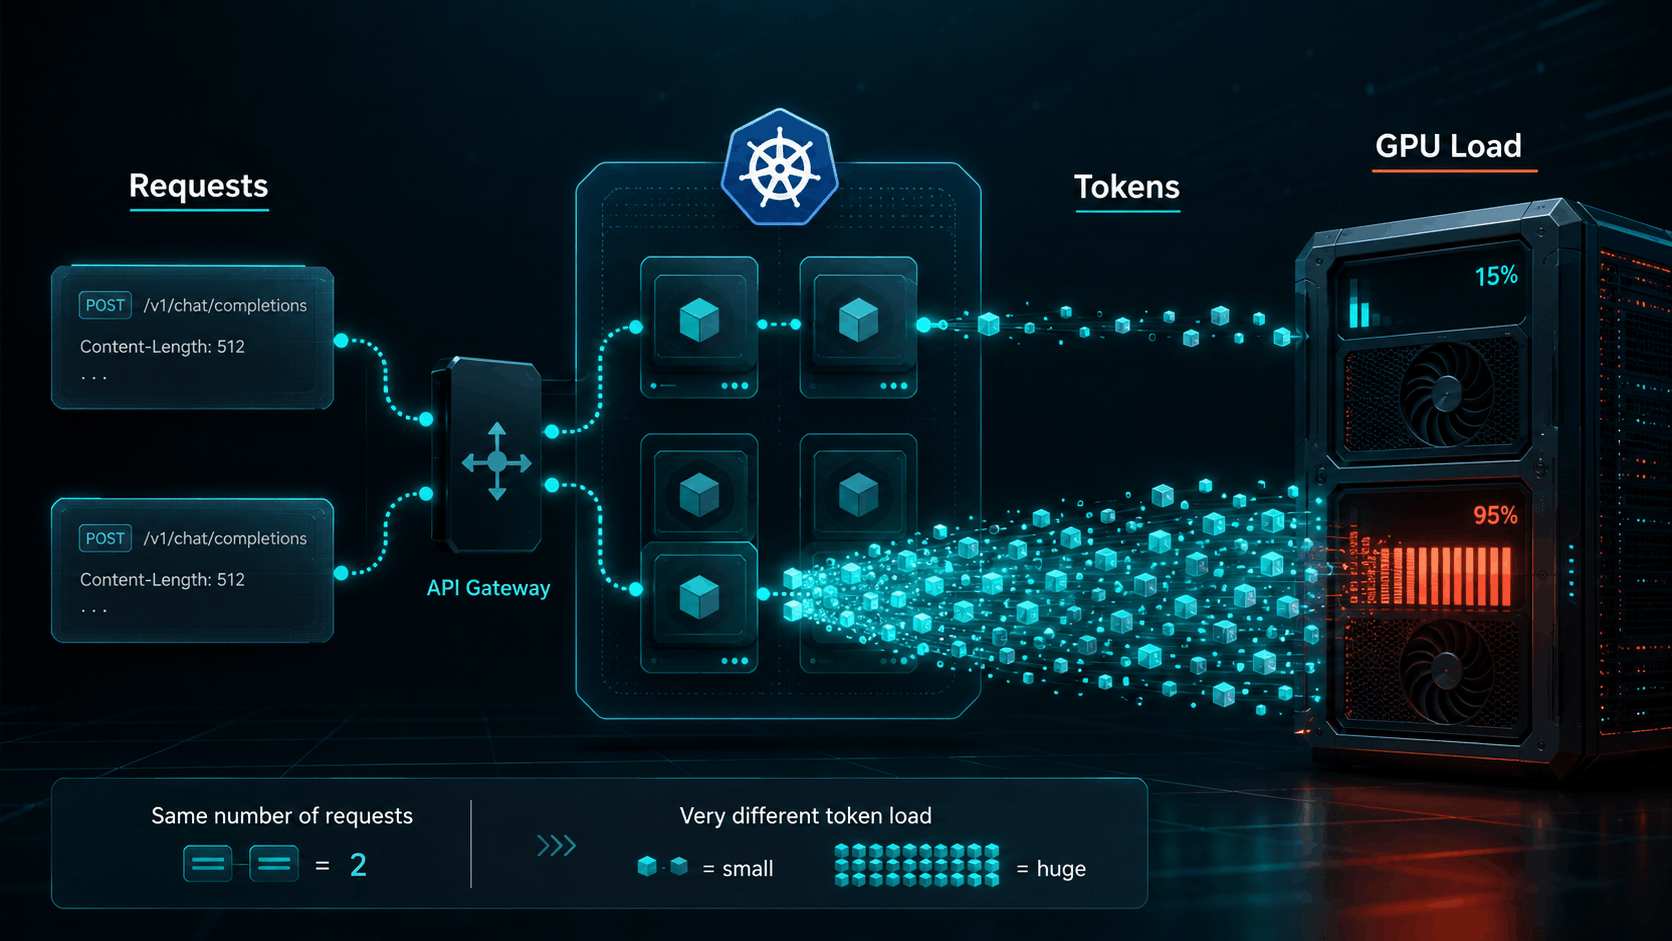
Request count works for normal web apps, but it breaks down when you serve LLMs on Kubernetes. Prompt length, output length, RAG context, KV cache pressure, GPU capacity, latency, and observability are all driven by tokens, not requests.
14 May 2026 09:00 AM
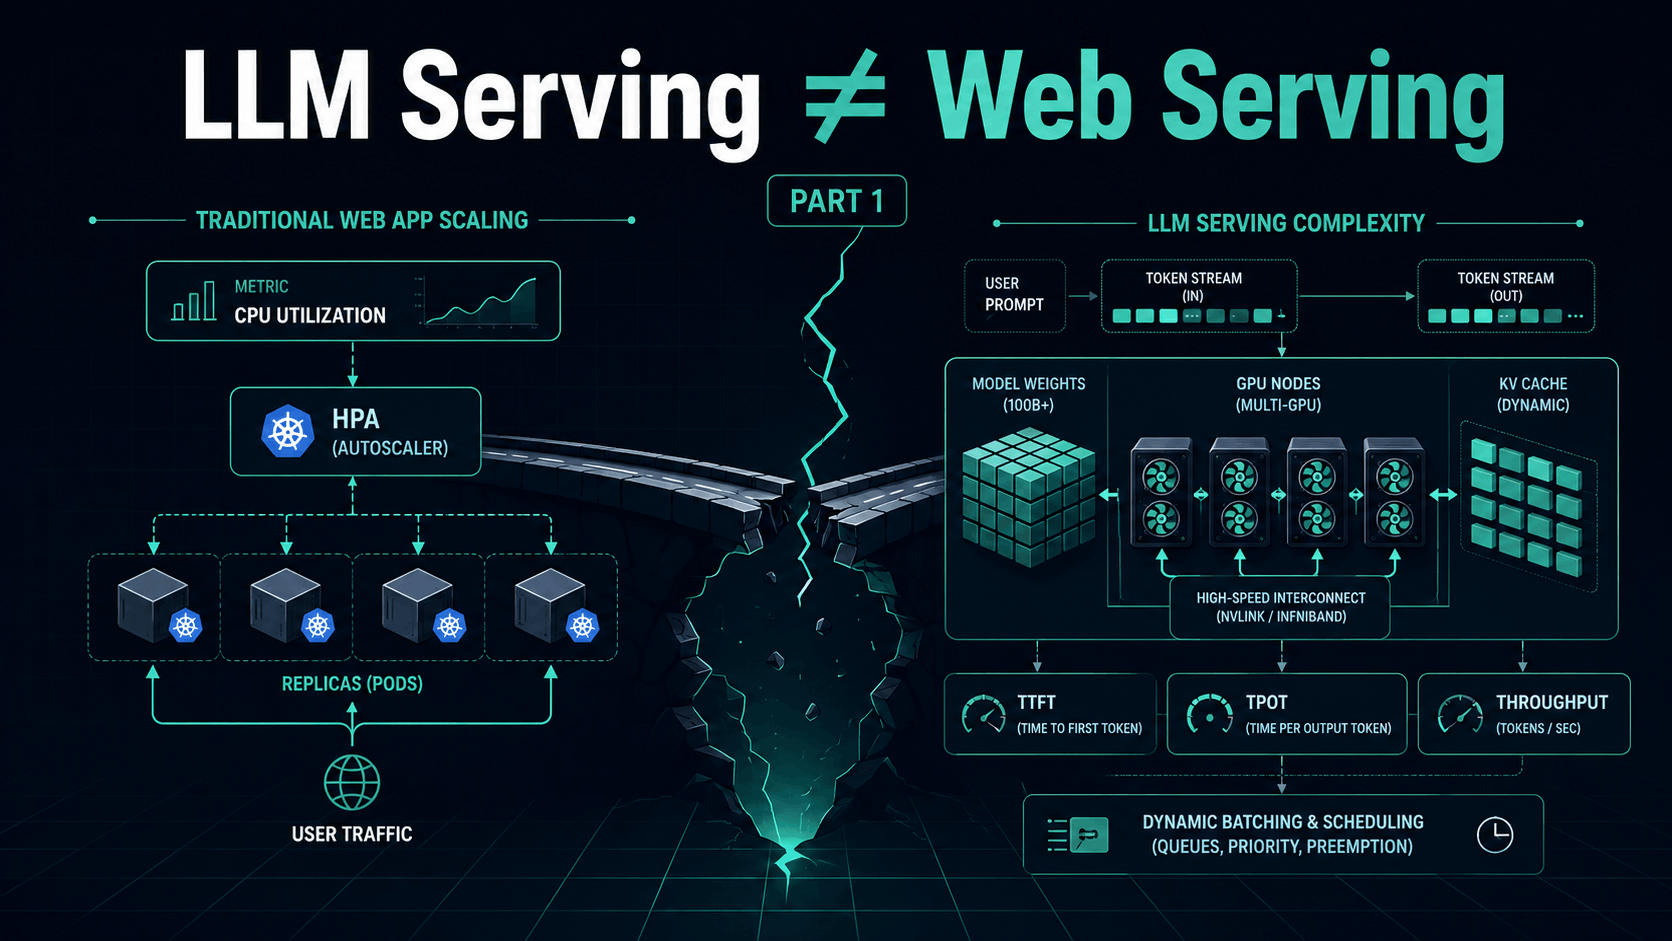
A practical introduction to why LLM serving breaks the usual web-app scaling playbook: requests become token streams, latency splits into TTFT and TPOT, replicas may span GPUs or nodes, memory becomes KV cache, and autoscaling needs workload-aware signals instead of CPU alone.
26 April 2026 07:49 AM
In the previous part, we set up cert-manager on a Kubernetes cluster and issued SSL certif...

24 October 2025 07:49 AM
Learn how to enable Basic auth for Prometheus ingress with ALB in Kubernetes by adding an NGINX proxy sidecar in kube-prometheus-stack Helm chart. Full guide with YAML examples, annotations, and best practices.
24 November 2021 03:04 PM
Kubernetes is an open-source system for automating deployment, scaling and management of c...